This is the long-form reference. For the five-minute skim version (quick table + router rules), see the companion blog.
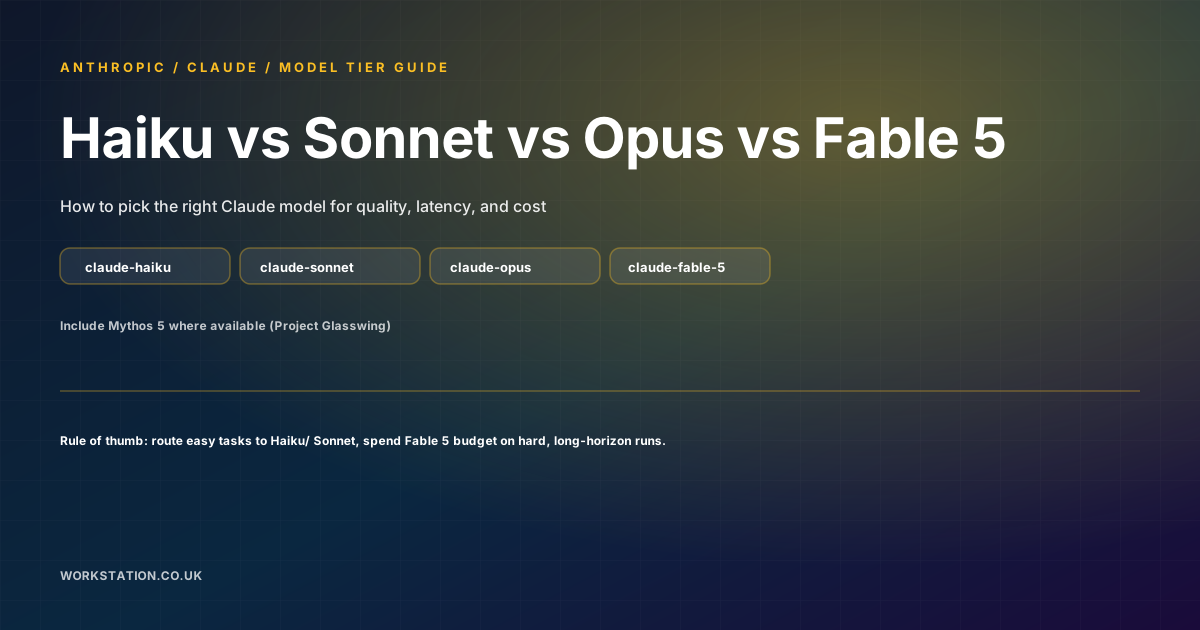
1. Why compare Claude models at all?
Most teams do not lose money because their prompts are bad. They lose money because they use the most expensive model for everything, or because they treat model choice like a vague preference instead of a budgeted product decision. Claude’s lineup is explicitly tiered: it is built so you can match task shape to the smallest model that will finish it well.
The practical outcome: model selection is one of the simplest levers you can pull to improve latency, quality, and cost per outcome at the same time.
2. The modern Claude lineup (2026)
All current Claude models support text and image input, multilingual capabilities, and vision, and they are available through the Claude API, Claude Platform on AWS, Amazon Bedrock, Google Cloud, and Microsoft Foundry.
2.1 Specs you should actually care about
| Model | API ID | Context window | Max output | Pricing (input / output) | Thinking behavior |
|---|---|---|---|---|---|
| Claude Haiku 4.5 | claude-haiku-4-5-20251001 (alias: claude-haiku-4-5) |
200K tokens | 64K tokens | $1 / $5 per MTok | Extended thinking available (adaptive off) |
| Claude Sonnet 5 | claude-sonnet-5 |
1M tokens | 128K tokens | $3 / $15 per MTok | Adaptive thinking always on |
| Claude Opus 4.8 | claude-opus-4-8 |
1M tokens | 128K tokens | $5 / $25 per MTok | Adaptive thinking always on |
| Claude Fable 5 | claude-fable-5 |
1M tokens | 128K tokens | $10 / $50 per MTok | Adaptive thinking always on |
Claude Mythos 5 (claude-mythos-5) is gated and shares the same specs and pricing as Fable 5, but it is paired with a different safety architecture (no safety classifiers in the same way as Fable 5). If you do not have access, you can still run essentially the same integration logic using Fable 5 where available.
2.2 Knowledge cutoff (why it matters for “current info”)
Anthropic’s model overview lists:
- Reliable knowledge cutoff: January 2026 for Fable 5 / Opus 4.8 / Sonnet 5; February 2025 for Haiku 4.5.
- Training data cutoff: broadly January 2026 for Fable 5 / Opus 4.8 / Sonnet 5; July 2025 for Haiku 4.5.
Practical take: if you need facts after the cutoff, use retrieval (RAG) or a tool, regardless of model tier.
3. What the tiers mean in practice
3.1 Latency and the output-token reality
Across the lineup, the token economics differ more by output than by input. A simple way to think about it:
- Haiku is cheapest (and fastest) when you want short structured answers.
- Opus and Sonnet spend more, but still scale well when your prompts are bounded.
- Fable 5 is expensive because it is meant for hard, long runs where the model needs to stay in scope over time.
If you let any model produce unbounded text, output tokens dominate spend. That is why max output (or strong instructions for TLDR-first) matters for all tiers, not just Fable 5.
3.2 Adaptive vs extended thinking
Anthropic’s overview table highlights two differences:
- Fable 5 / Opus 4.8 / Sonnet 5 have adaptive thinking always on.
- Haiku 4.5 has extended thinking available, but adaptive thinking is off.
Practical take: use Haiku for high-volume tasks, but be mindful that it is not optimized for the same long-horizon “always adapt” behavior. When you hit ambiguity or deep planning needs, step up to Sonnet/Opus/Fable.
3.3 Effort as a cost-quality dial
Effort is the primary control for the trade-off between intelligence, latency, and cost on Fable 5 and Mythos 5. Opus 4.8 and Sonnet 5 also expose effort control on the API surfaces.
Practical implication: the most common migration mistake is not “wrong prompt”. It is “maxing effort everywhere.” For most production workloads, you get the best value by routing effort deliberately (cheap tasks at low/medium, hard tasks at higher effort).
4. A decision matrix you can implement
Instead of asking “Which model is best?”, ask “Which model can finish this workflow with the fewest expensive tokens?”
| Task shape | Choose | Why |
|---|---|---|
| Intent classification, routing, entity extraction | Haiku | Fast, cheap, and ideal for high throughput |
| Daily coding help, documentation, structured reasoning | Sonnet | Best speed/quality balance |
| Complex agentic coding, enterprise analysis, deep debugging | Opus | Strong performance on long and multi-step enterprise tasks |
| Days-long agent runs, multi-document synthesis with delegation | Fable 5 (or gated Mythos 5) | Designed for long-horizon autonomy and staying in scope |
5. Routing blueprint for production (cheap -> smart -> frontier)
This is a practical pattern that works well when you have a mixture of tasks: some easy, some hard, and a lot of “mostly easy but occasionally tricky”.
5.1 Step-by-step router
- Classify with Haiku. Determine intent and rough complexity; also estimate whether you need long context or tool use.
- Run the main path on Sonnet or Opus. Sonnet for most “serious but bounded” tasks. Opus when you expect complex agentic coding or deeper debugging.
- Escalate to Fable 5 for true long-horizon work. Examples: cross-repo refactors, multi-document synthesis where the model must keep multiple constraints alive, and autonomous runs that delegate subtasks.
- Handle fallback/refusals. If Fable 5 refuses due to safety classifiers, fall back to Opus 4.8 (or another appropriate model) depending on your product requirements.
5.2 Budget the router (do not let escalation erase savings)
A router can be cost-effective only if escalation is rare. Add constraints so the expensive tier cannot balloon:
- Set max output tokens on every tier.
- Use TLDR-first instructions so the model can stop early when enough is known.
- Cache stable prefixes (system prompt and tool schemas) to reduce repeated input costs.
6. Token economics you can use as a sanity check
Because pricing is per token, you can approximate cost per request. Using the model overview pricing values:
- Fable 5: $10 input / $50 output per MTok
- Opus 4.8: $5 input / $25 output per MTok
- Sonnet 5: $3 input / $15 output per MTok
- Haiku 4.5: $1 input / $5 output per MTok
Rough formula (plug in your estimates):
cost ~= (input_tokens / 1_000_000) * input_price
     + (output_tokens / 1_000_000) * output_price
Sanity rule: if output tokens are large, Fable 5 becomes the dominant cost driver quickly. That is why prompt structure and output caps matter more than many teams expect.
7. Prompting patterns across tiers
Most prompting best practices apply to every Claude model: provide clear goals, constrain output format, and only ask for what you need. The tier-specific differences show up in how you control length and control effort.
7.1 General rules that prevent budget leaks
- Lead with the outcome. Your first line should say what happened or what you found.
- Request TLDR-first. Let the model stop early when it can.
- Cap scope creep. Do not ask for extra features, refactors, or “nice to have” improvements unless requested.
- Bound output length. Use max output tokens or strict formats.
7.2 When Fable 5 changes the job
Fable 5 is built for long-horizon autonomy: it can sustain productive output over extended periods, delegate subtasks, and stay coherent when the task is truly multi-step. The prompting difference is not just “more reasoning.” It is that you can (and should) structure workflows as goals + checkpoints + tool-driven evidence, instead of forcing everything into a one-shot answer.
8. Example workflows (what to use where)
8.1 Haiku 4.5
- Classify incoming requests (intent + complexity) and route to the right tier.
- Extract structured fields into JSON for downstream systems.
- Summarize short passages with a strict schema and max output cap.
8.2 Sonnet 5
- Refactor and explain code with a “what/why/how” format.
- Draft customer-facing content with consistent tone and short outputs.
- Build agent tooling that still needs speed (tool calling + short loops).
8.3 Opus 4.8
- Complex agentic coding: multi-file changes, deeper debugging, and more careful system-wide reasoning.
- Enterprise document analysis: spreadsheets, slides, and long reports.
- Hard-but-bounded tasks where you still want an enterprise-grade answer, not just a sketch.
8.4 Fable 5 (and Mythos 5)
- Days-long code migrations across repos with tool use and verification steps.
- Multi-document synthesis where instruction retention and coherence over long runs are essential.
- Autonomous workflows that delegate sub-tasks and continue after intermediate results.
9. Migration notes
9.1 Migrating to Opus 4.8
If you are currently on Opus 4.7 or earlier, start by:
- Ensuring you set
effortexplicitly when you have latency or budget requirements. - Reviewing any prompt skills that may be over-prescriptive. Higher capability can amplify overly-specific instructions.
- Re-testing output length assumptions and applying max output caps where needed.
9.2 Migrating from Opus to Fable 5
Fable 5 is not a “faster Opus.” Treat it as a workflow tool for long-horizon tasks:
- Move to goal + checkpoint structuring (especially for agentic runs).
- Delegate subtasks instead of stacking everything in one long thread.
- Use caching and bounded output so long runs do not inflate spend.
10. Common gotchas
- Using Fable for everything. It is meant for the hard, long-horizon cases.
- No output caps. Even Haiku can get expensive if you let it generate unbounded text.
- Assuming context windows are interchangeable. Haiku has 200K tokens; the others default to 1M.
- Ignoring cutoff differences. If you need post-cutoff info, use retrieval/tools.
- Not routing effort. Setting max effort everywhere often increases cost without improving outcomes.
11. Bottom line
Claude’s lineup is designed so you can build a model router that matches the smallest capable tier to each task shape. Start with Haiku for cheap routing and extraction. Use Sonnet for the majority of daily work. Escalate to Opus for complex enterprise and agentic coding. Reserve Fable 5 (and gated Mythos 5) for the true long-horizon runs that require sustained autonomy and coherence.
When in doubt, keep your prompts bounded, cap output length, and measure output tokens per outcome. That one metric tends to make model choice obvious.
SEO snapshot for this article
- SEO title: Claude Models Compared: Haiku vs Sonnet vs Opus vs Fable 5 (Mythos 5)
- Meta description: Compare Anthropic Claude Haiku, Sonnet, Opus, Fable 5, and gated Mythos 5. Includes specs, cost/tokens strategy, routing blueprint, and when to use each tier.
- Primary keywords: Claude models comparison, Claude Opus 4.8, Claude Fable 5, Claude Sonnet 5, Claude Haiku 4.5, Claude Mythos 5, token budgeting, agentic coding
- Twitter / X: Claude model tiers explained: Haiku for cheap routing, Sonnet for daily work, Opus for complex coding, Fable 5 for days-long agentic runs. Token-budget routing blueprint inside.
- LinkedIn: A practical, implementable comparison of Anthropic Claude Haiku, Sonnet, Opus, Fable 5, and gated Mythos 5. Specs, cost model, and a router that keeps output tokens under control. From Workstation.