Key takeaways
- Complementary roles for generative models and decision models in production AI systems.
- Read with the Benchmark Lab open.
- Prefer primary sources.
Why this matters
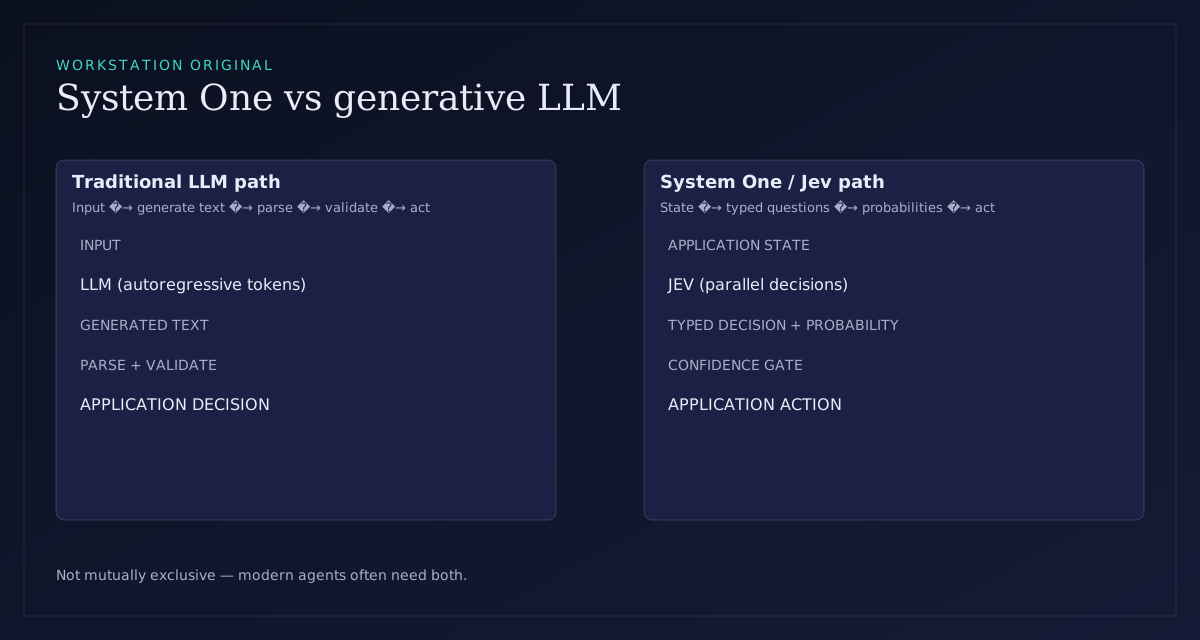
Complementary roles for generative models and decision models in production AI systems.
Deep dive
See also the long-form essay and interactive lab for full tables and citations.
System One vs LLMs — detailed note 1. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 2. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 3. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 4. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 5. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 6. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 7. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 8. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 9. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 10. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 11. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 12. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 13. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 14. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 15. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 16. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 17. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
System One vs LLMs — detailed note 18. In production AI, comparison choices should be evidenced with paired evaluations, explicit latency definitions, and clear separation between vendor claims and independent measurements. Workstation repeats this discipline across Insights pages so engineers can trust the surrounding narrative when they deep-link from Jobs, Agents, or Automation pages. When in doubt, open the Benchmark Lab filters and read the “what this does not prove” panel before citing a number externally.
Conclusion
Return to the series hub for the full path.
Related on Workstation
- Benchmark Lab — Interactive charts
- Model selection manual
- AI Agents
- AI Automation
- Jobs
Sources
- TypeSafe AI — Introducing System One Models & Jev — Primary vendor source (15 Sep 2026).
- LangChain — Building a Harness with Jev — Harness integration (17 Sep 2026).
- TypeSafe documentation index — Concepts, primitives, API, cookbooks.
- LangChain — Can Jev Be a Better Agent Evaluator? — 20 Sep 2026 LangSmith experiment.
- OpenRouter — Jev vs LLM when to use each — Published triage cost/latency/accuracy.
- AyAutomate — Independent Jev benchmark — 791 decisions; challenges headline multipliers vs small models.
- JevBench RESULTS v1.2 — Public community harness.
- OpenAI — Introducing the Agents API — Landscape: agent platform primitives.