Der Workstation-Blog
LLM
Beiträge mit dem Tag LLM.
MCP for DevOps: Give Agents Pipeline Context Without the Keys
How platform teams can use the Model Context Protocol safely: start with read-only servers and scoped identities behind a gateway, trace every tool call, and add write tools only behind human approval. Includes RBAC, tool and task examples.
Gemini 4 Argon: Was es für Ihr Team bedeutet und wo Sie es zuerst einsetzen sollten
Gemini 4 Argon ist dafür gebaut, stundenlang an einem messbaren Problem zu arbeiten. Hier erfahren Sie, was veröffentlicht wurde, was es wirklich kostet und wie Sie es sicher an Ihrem eigenen Backlog erproben.
 Balinder WaliaLesen
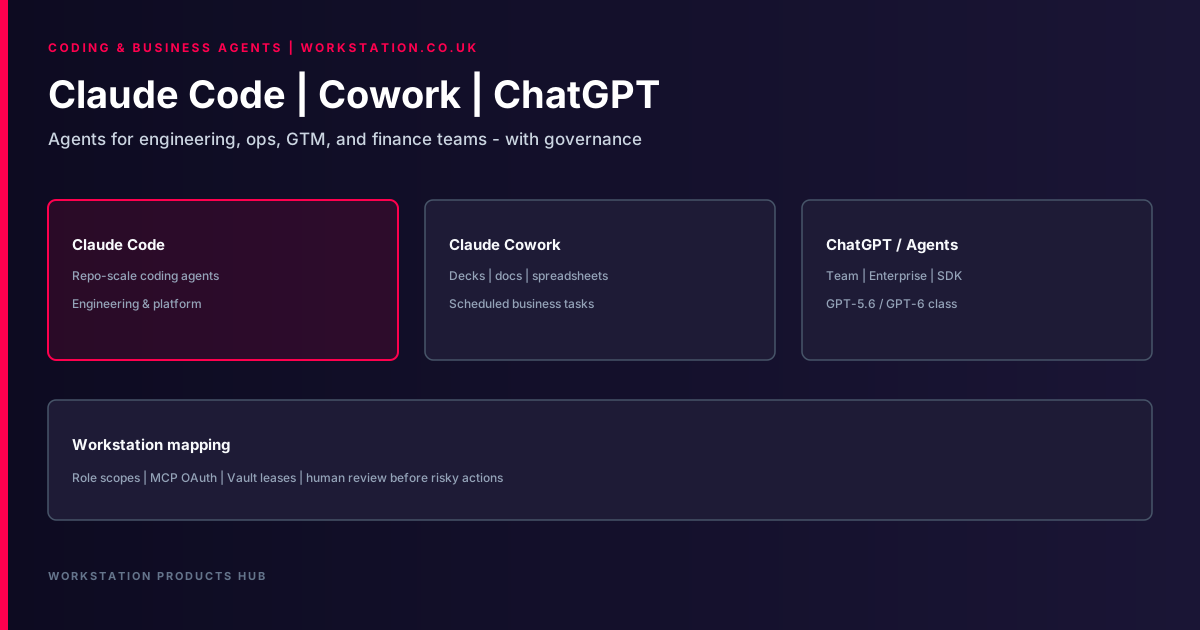
Claude Code, Claude Cowork & ChatGPT for Business Teams
Which teams should use Claude Code, Claude Cowork, or ChatGPT/OpenAI Agents — and the controls Workstation recommends before production.
Balinder WaliaLesen 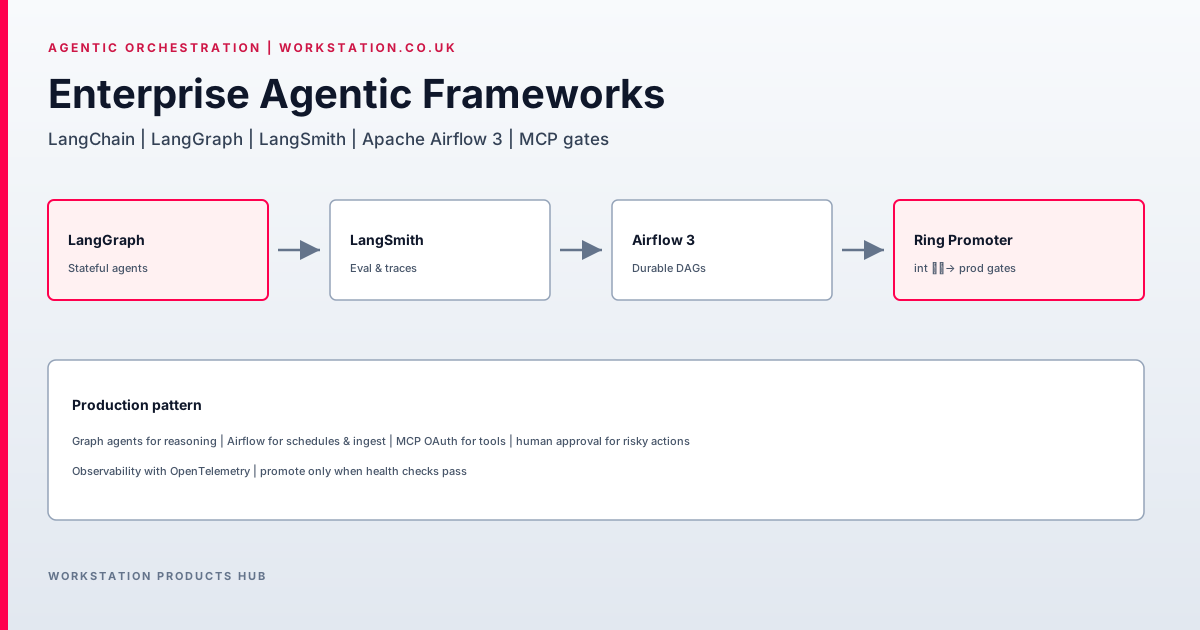
Enterprise Agentic Frameworks: LangChain, LangGraph & Airflow 3
Operational guide to LangGraph agents, LangSmith evals, and Apache Airflow 3 schedules — with Workstation promotion and edge patterns.
Balinder WaliaLesen 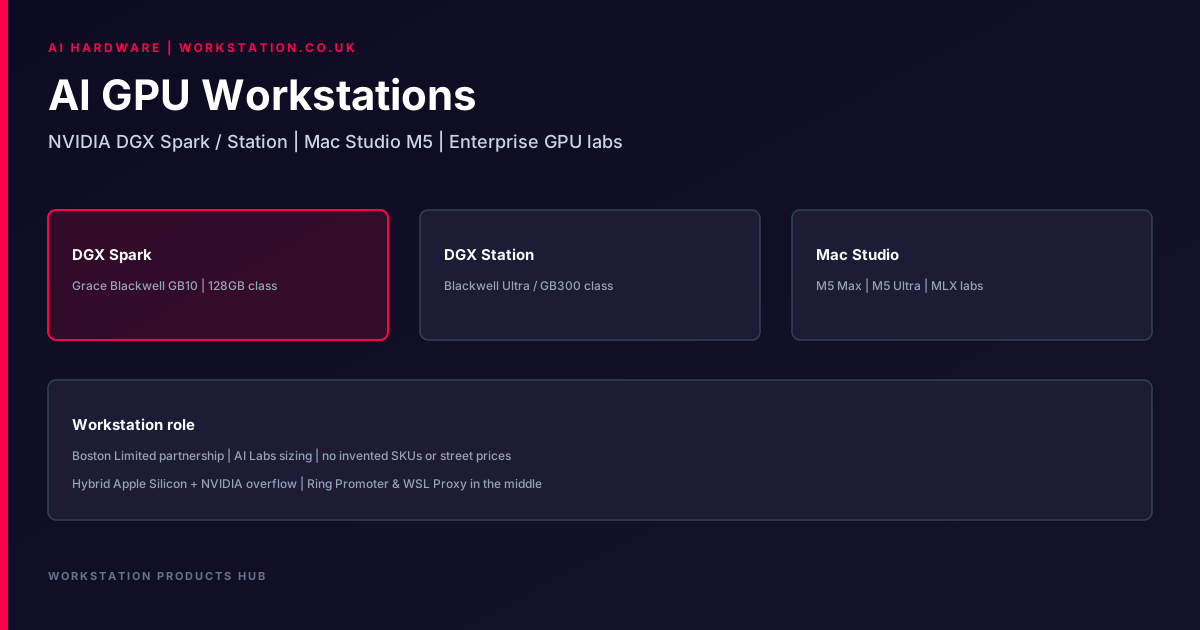
AI GPU Workstations: NVIDIA DGX Spark/Station & Mac Studio M5
How Workstation maps NVIDIA DGX Spark, DGX Station, and Mac Studio M5 into AI Labs and SME packages — factual positioning, no invented prices.
Balinder WaliaLesen 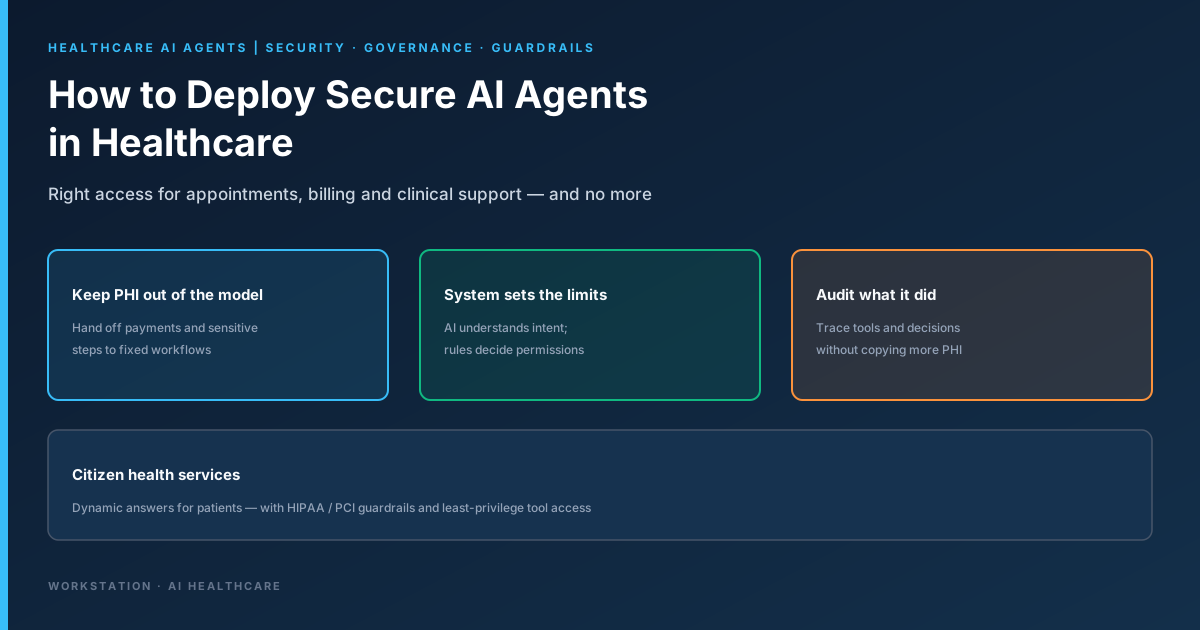
How to Deploy Secure AI Agents in Healthcare
AI agents can book appointments, take payments and support clinical work. Here is how healthcare teams can give them the right access, and no more.
Balinder WaliaLesen 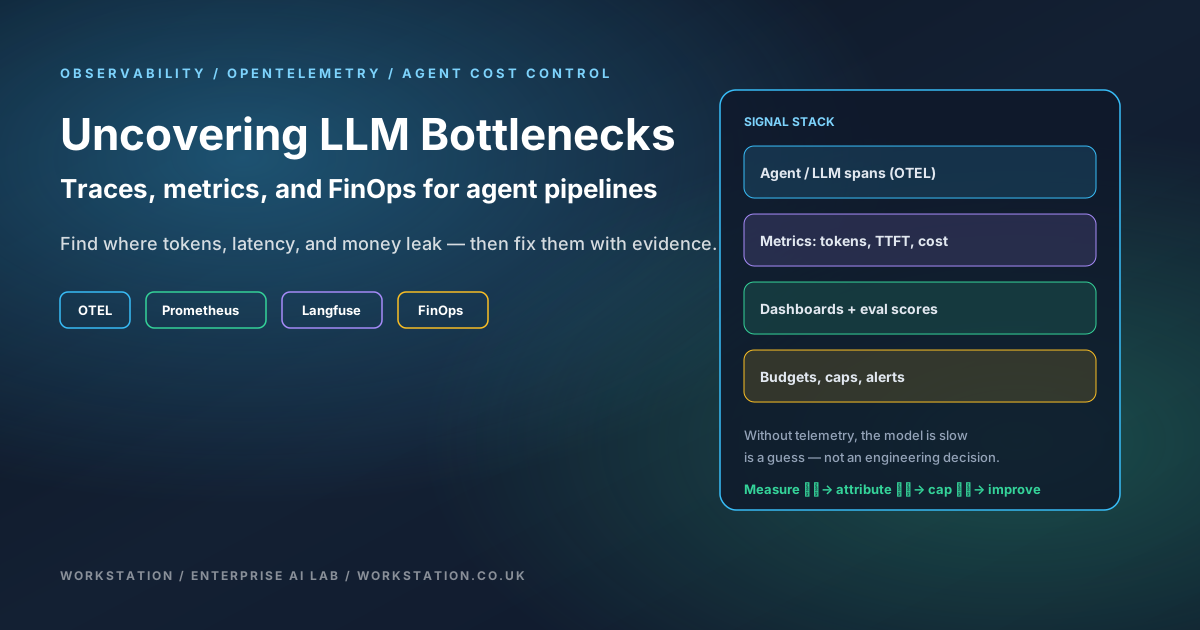
Uncovering LLM Bottlenecks: Observability, OTEL & Cost Control
Workstation on uncovering LLM agent bottlenecks with observability: OpenTelemetry, Prometheus/Grafana/Thanos, Langfuse — with clear pros/cons, cost levers, and usage metrics that protect margins.
Balinder WaliaLesen 
Turbocharging LLMs
Workstation on turbocharging LLMs: PagedAttention paging for KV cache, vLLM serving, Self-Debugging for agents, PowerInfer token rates, and EG-MLA memory cuts — with production trade-offs.
Balinder WaliaLesen