The Workstation Blog
LLM
Posts tagged LLM.
AI Developer Laptops: Why Every AI Team Should Give Developers Their Own GPU
Every software team is now an AI team. Giving AI developers a Linux laptop with a serious GPU makes them faster, keeps code and data private, and makes AI costs predictable. The business case, honest cost numbers, who needs which configuration and how to roll it out.
 WorkstationRead
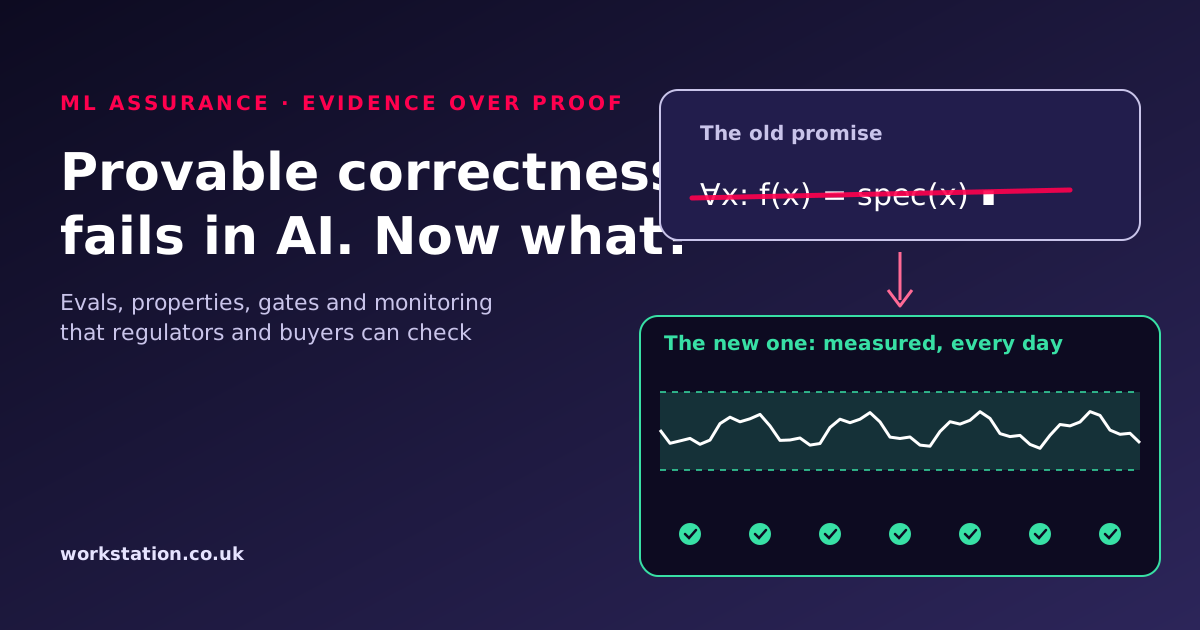
Provable Correctness Fails in AI: What Evidence to Build Instead
ML models cannot be proven correct the way code can: nobody can write down what correct means for every input. Here is the evidence to build instead, from slice metrics and property tests to LLM output contracts, release gates and monitoring.
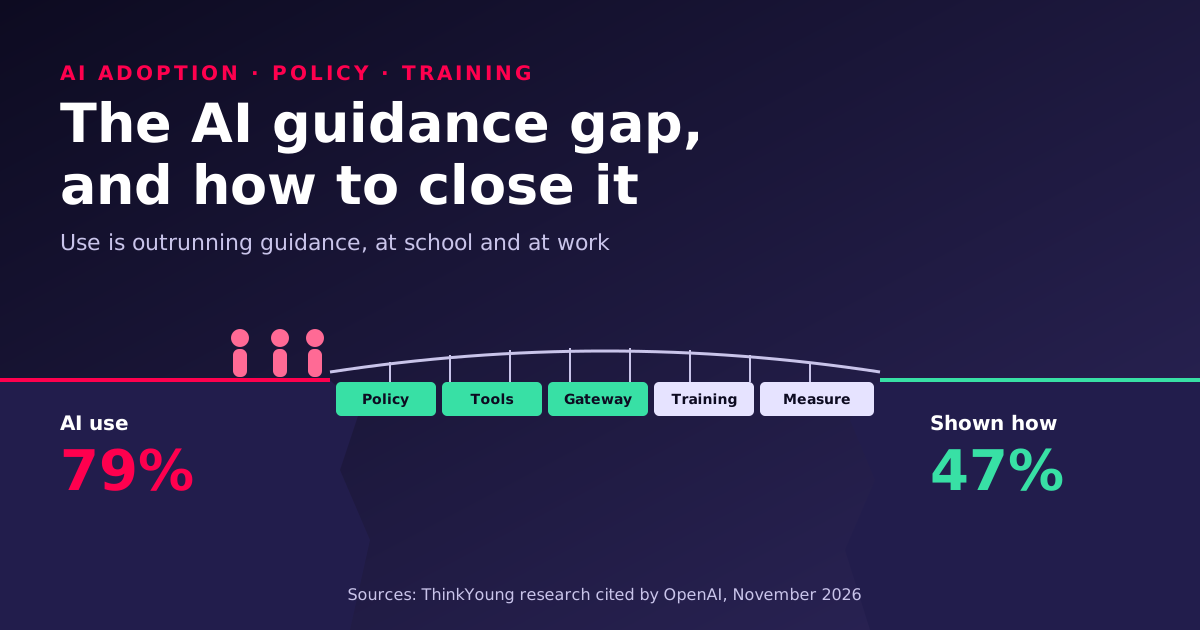
The AI Guidance Gap: Use Outpaces Training at School and at Work
79% of students use AI for homework but only 47% were shown how, according to ThinkYoung research cited by OpenAI. Workplaces show the same gap. A 90-day playbook for business leaders: policy by data class, approved tools, a gateway, role-based training and usage metrics.
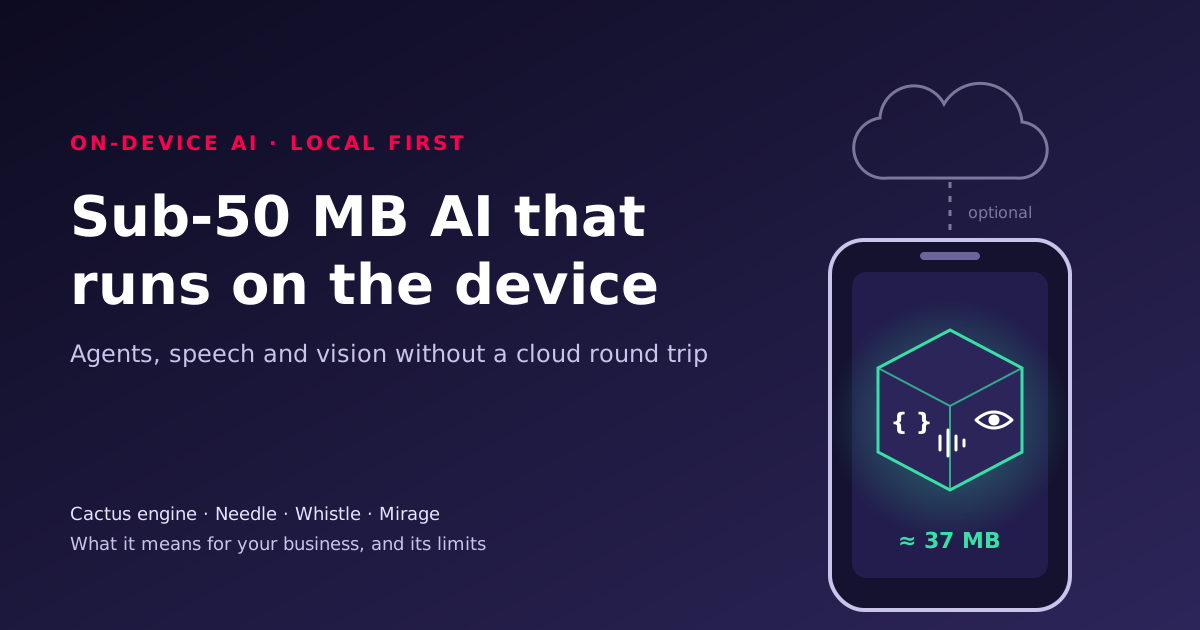
Sub-50 MB On-Device AI: What Cactus's Engine Means for Business
Cactus Compute's open-source engine (not NVIDIA's, as first reported) runs tool calling, speech and vision models under 50 MB each on phones and laptops. What it is, what we measured, its limits, and which AI tasks belong on the device.
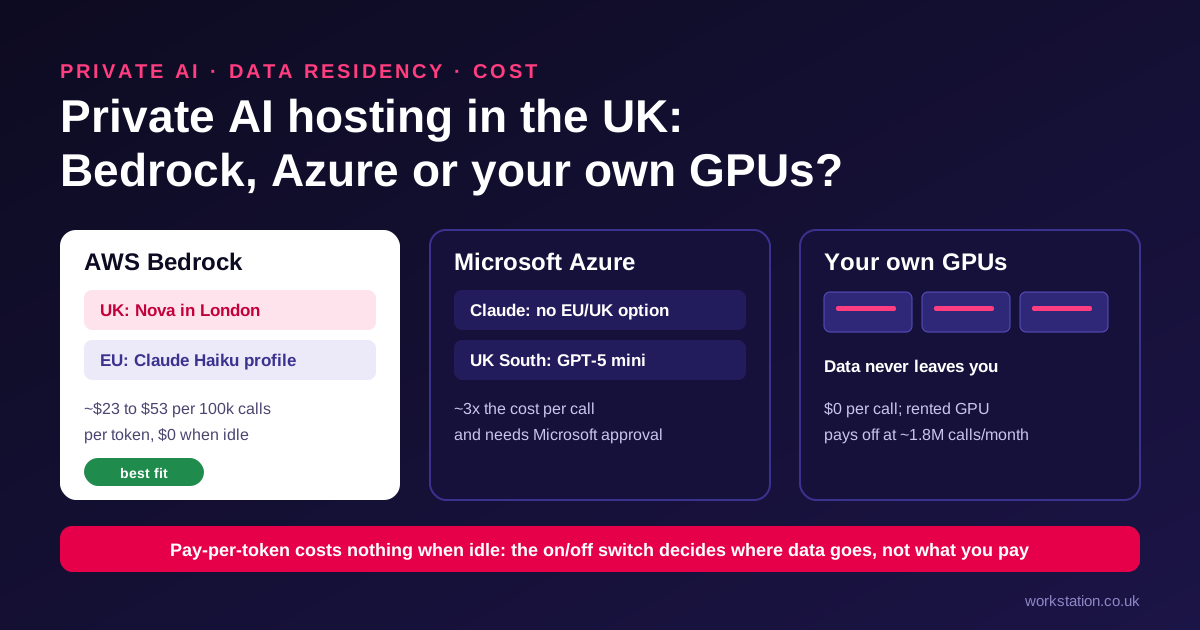
Private AI Hosting in the UK: AWS Bedrock vs Microsoft Azure vs Your Own GPUs
Where is customer financial data processed, and what does each AI call cost? A comparison of AWS Bedrock, Microsoft Azure, UK and EU AI providers and your own GPUs for a typical UK finance workload, with costs at three volumes, a data-residency workflow and the break-even point for a dedicated GPU.
WorkstationRead 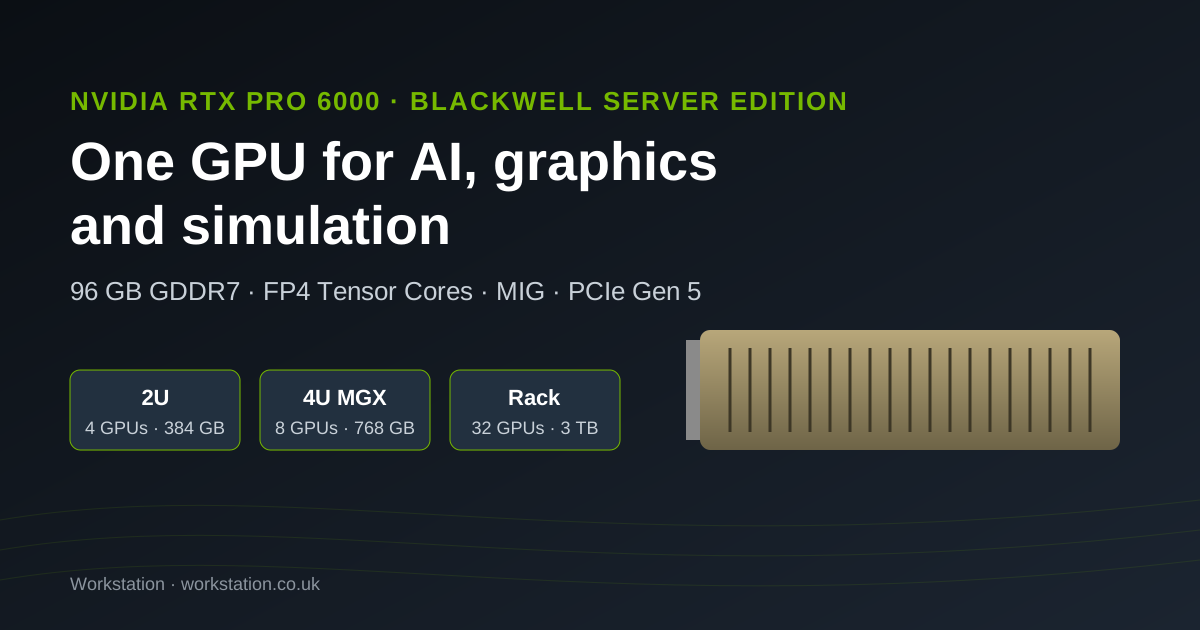
NVIDIA RTX PRO 6000 Blackwell Server Edition: One GPU for AI, Graphics and Simulation in a UK Server Room
96 GB of GDDR7, FP4 Tensor Cores and RT Cores in a standard PCIe card: what NVIDIA's RTX PRO 6000 Blackwell Server Edition does, why it suits companies running private AI in rooms they already have, the three system sizes from a four-GPU 2U server to a 32-GPU rack like AMAX's RackScale 32, and what to check before ordering.
Balinder WaliaRead 
Build AI Agents with NebulaDB: Semantic Search, RAG and a Visa AI Agent
How we built semantic search, RAG and a Thai Visa AI Agent on NebulaDB, with real queries, query plans and retrieval scores measured on our 8.3M-document production server, and the guards that keep private data and invented numbers out of the answers.
Balinder WaliaRead 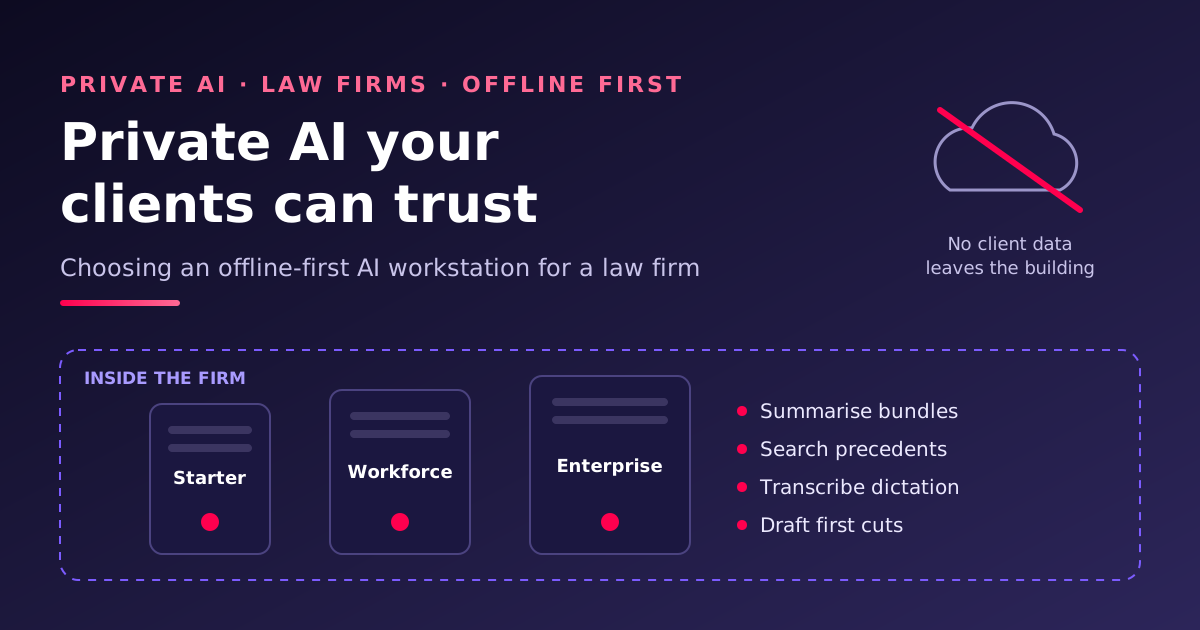
Private AI for Law Firms: Choosing an Offline-First Workstation Your Clients Can Trust
How a law firm chooses a private-AI workstation that runs with no internet connection: who uses it, which model, how much GPU memory, how isolated it must be and who sets it up. With real prices from a real quote, where it was over-specified, and the Starter, Workforce and Enterprise builds we would actually ship.
Balinder WaliaRead 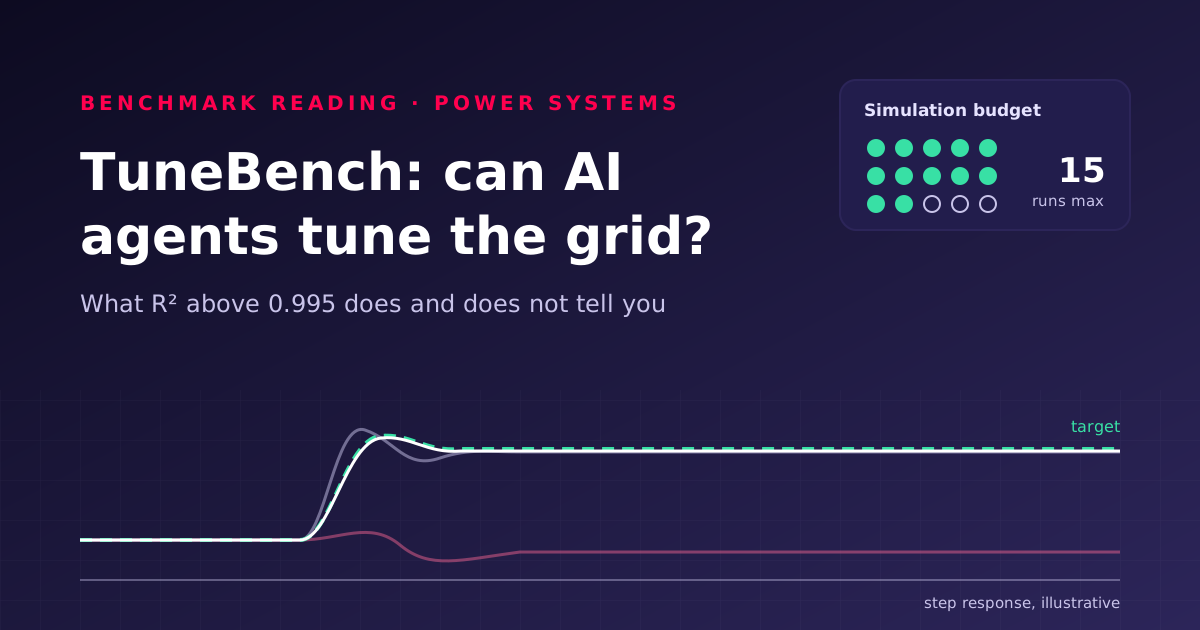
TuneBench: How Well Can AI Agents Calibrate Power System Models?
TuneBench tests LLM agents on calibrating generator and battery models within 15 simulations. Only Opus 5.5 and GPT-6 hit median R² above 0.995 in every test. What that figure means, its limits, and how to build the same kind of benchmark.